AI Agent Cost Optimization: The First-Request Cache Miss Audit That Cut Inference Spend 68%
AI agent cost optimization starts before model-switching. Audit cache misses, call loops, and effort levels to cut inference spend without sacrificing quality.
TL;DR: AI agent cost optimization is not primarily a model-selection problem. The framework used in this guide identifies three instrumentation gaps, cold-start cache misses, ungoverned call loops, and over-assigned effort levels, that silently inflate inference spend before model switching is ever necessary. Fixing them in sequence, with blinded-judge quality gates, is the highest-leverage path to lower costs without degrading output quality.
Key Takeaways
- First-request cache miss is the real culprit: Session-level measurement is a far more honest diagnostic than aggregate hit rate.
- Calls per run exposes runaway loops: Production distributions reveal ungoverned retries that silently inflate monthly spend.
- Effort level governs reasoning depth per call: Agents can assign heavy reasoning to low-stakes tasks without any governance check, quietly wasting budget.
- Blinded-judge tests protect quality during cuts: Blind side-by-side evaluation confirms you are not trading output quality for a lower invoice.
- Caching strategy must be rebuilt for multi-turn agents: Single-turn prompt caching tools break on shifting agentic context windows.
- Model switching is the last lever, not the first: The biggest savings opportunities come from fixing how and when your existing model is called.
Introduction
As of 2026, model prices have dropped, yet per-workflow costs keep climbing because agents make more calls, run longer reasoning chains, and spawn sub-agents. AWS now publishes a formal Agentic AI Well-Architected Lens with an entire cost-optimization pillar dedicated to this problem. Agentic AI changes not just what AI does but how costs are generated, requiring cost-aware design rather than simple per-call pricing analysis. The three-part audit in this guide is an author synthesis of the instrumentation gaps that aggregate dashboards consistently fail to surface.
Why does your aggregate cache hit rate lie about your real AI agent costs?
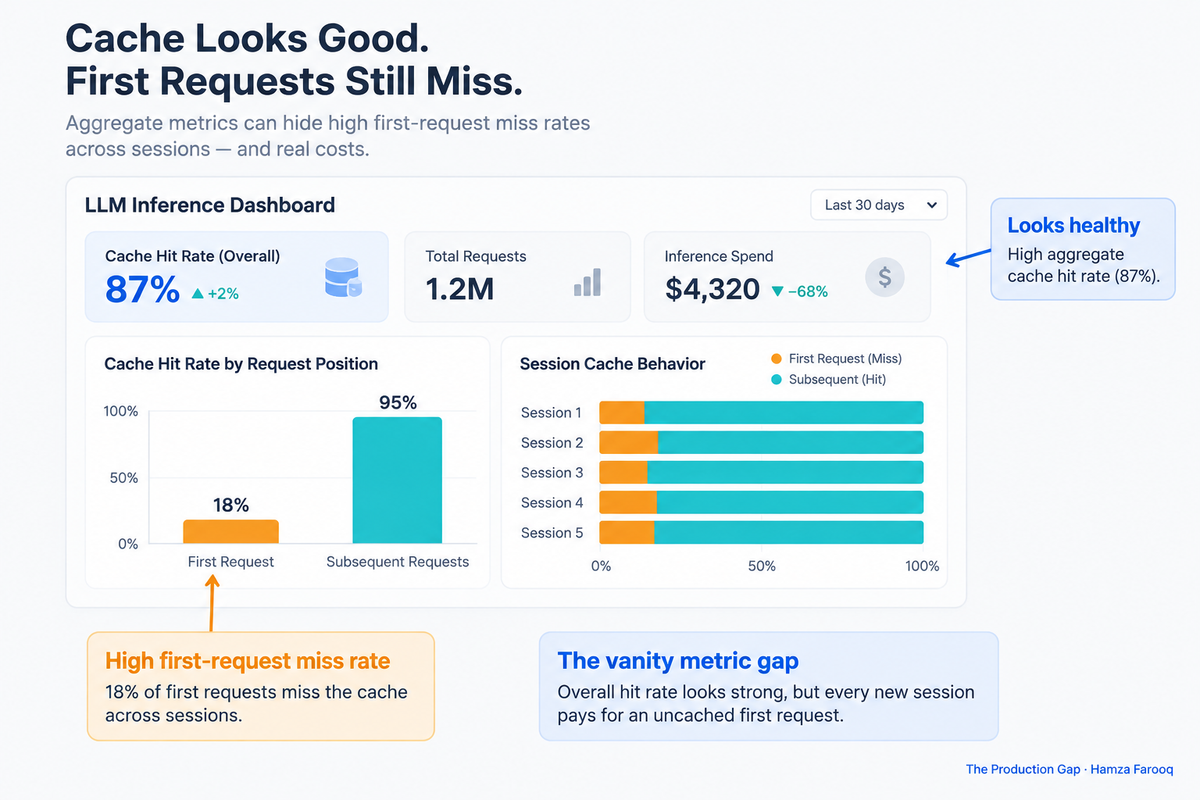
Aggregate cache hit rate is a vanity metric for agentic workloads because it averages hits across all calls, masking that the first call of every new session almost always misses cold. That cold miss is where a disproportionate share of inference spend accumulates.
If a 10-call agent session hits cache on calls 2 through 10 but misses on call 1, the dashboard shows 90%. The bill does not shrink proportionally. The diagnostic that actually matters is the session-level first-request cache miss rate: the percentage of sessions where the very first LLM call is served cold, which almost no cost dashboard surfaces by default.
Agentic workloads make this worse because shifting context windows in multi-turn sessions break the prompt-prefix assumptions that single-turn caching tools rely on. The AWS Agentic AI Well-Architected Lens names caching and spend attribution as explicit cost-optimization design principles, which signals how widely this gap goes unaddressed in practice.
How do you run the three-part cache miss audit on your own agent pipeline?
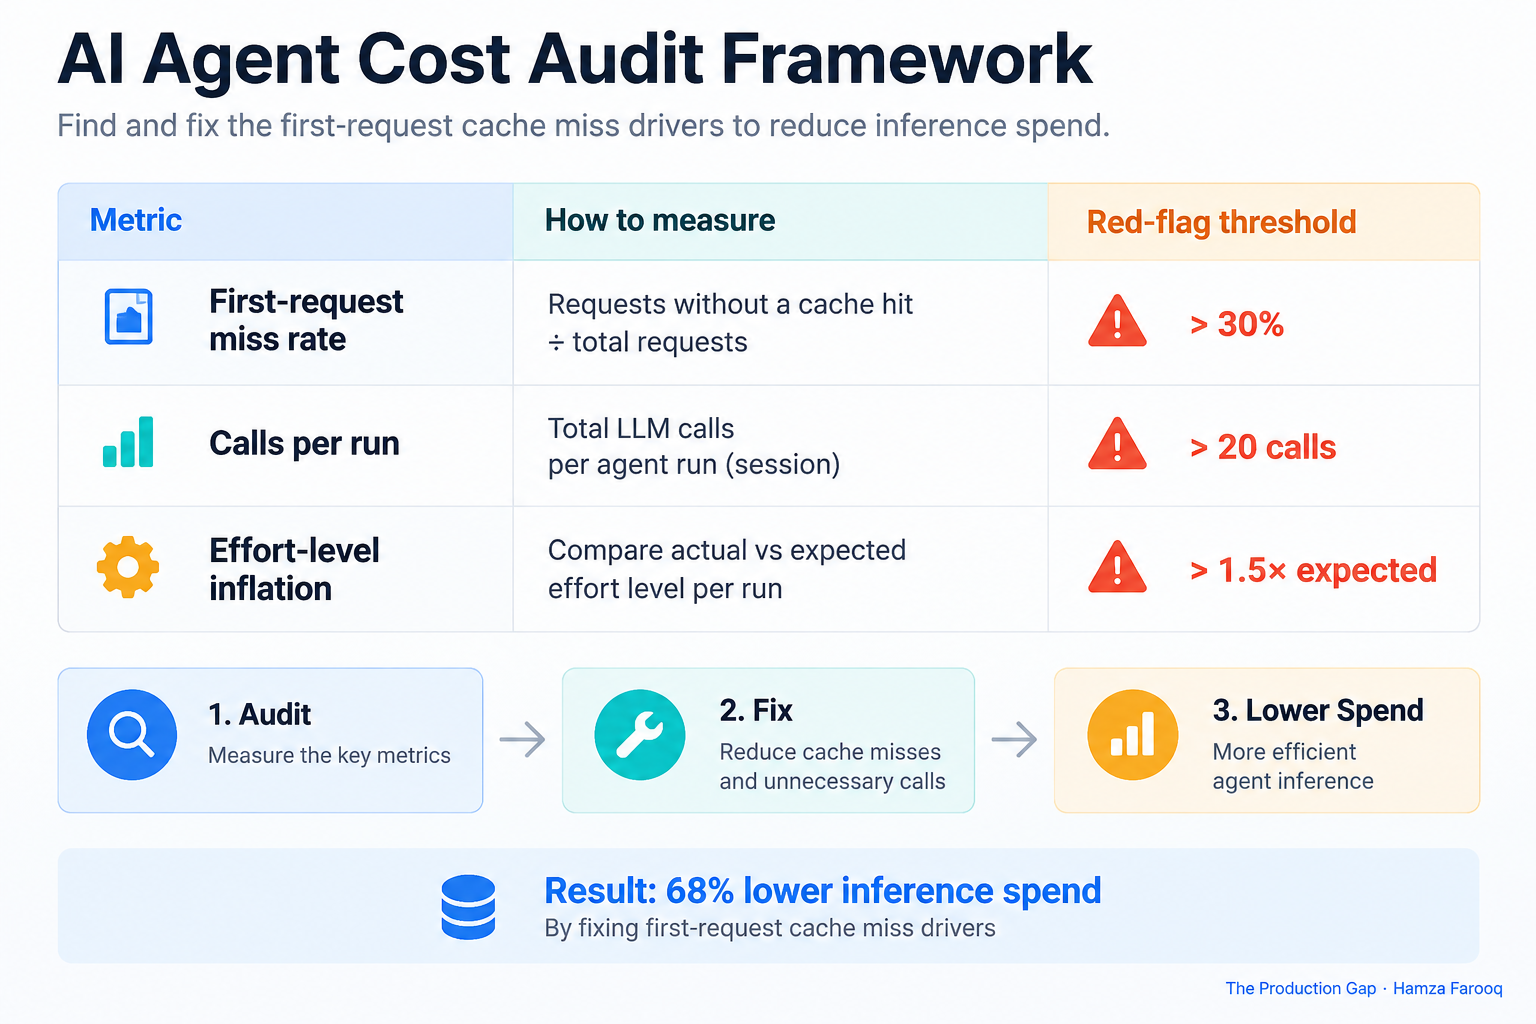
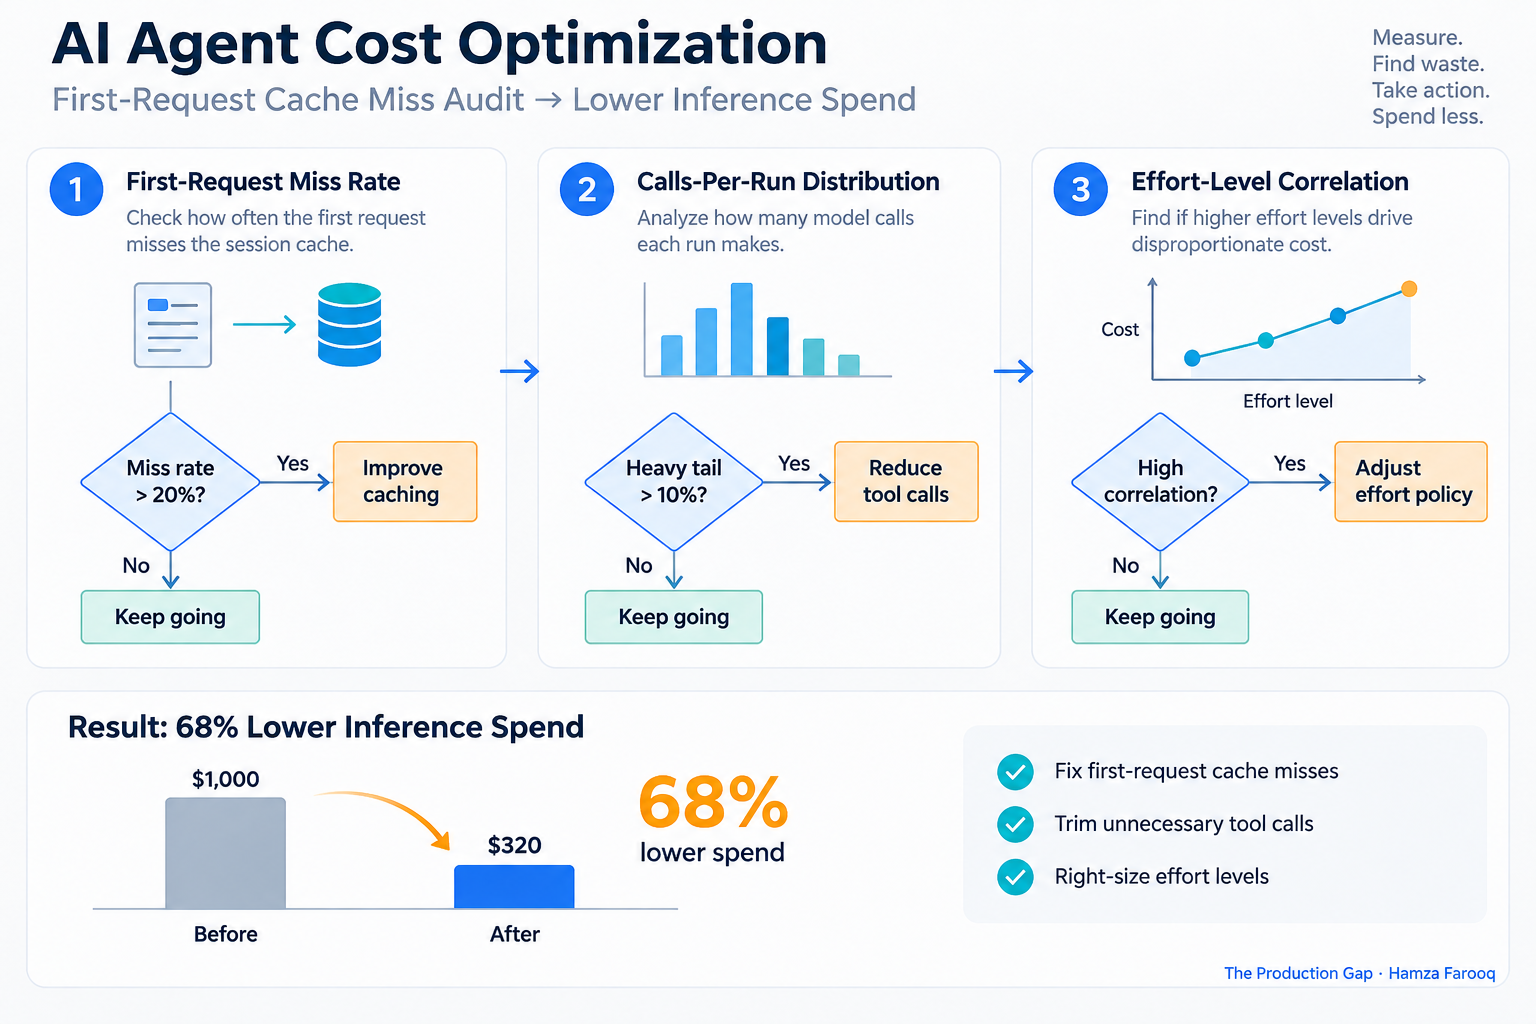
The audit has three sequential measurements, session-level first-request miss rate, calls-per-run distribution, and effort-level versus real-finding correlation, each exposing a different category of hidden cost that aggregate metrics bury. This three-part structure is the framework used in this guide, not an externally published standard.
Step 1: Measure first-request miss rate per session
Tag each LLM call with a session ID and sequential call index. Query logs for all records where call index equals 1, then calculate that subset's cache hit rate. A high miss rate on that filter means your caching layer provides no benefit at the moment every new session begins. You are paying full inference price at the most frequent cost event in your system. This query runs against existing logs and is, as a practical rule of thumb, the highest-leverage diagnostic in the audit.
Step 3: Correlate effort level to real findings
Effort level refers to the reasoning depth or compute budget assigned to a single LLM call within an agent run. Sample recent agent runs. For each, record the assigned effort level and whether the output contained a finding a lower-effort call could not have produced. That ratio is your effort inflation rate. This failure mode rarely appears in any standard observability view, which is why it persists.
What does effort-level calibration actually save, and how do you protect quality?
Effort-level calibration, routing simple requests to a lighter reasoning configuration without changing the model, can save more than model-switching when most production agents over-assign high-effort reasoning to tasks that do not warrant it.
In a code review agent, assigning maximum-severity reasoning to a linting warning costs the same as applying it to a logic vulnerability. Recalibrating effort assignment, rather than switching models, is the lever worth pulling first. AI agent cost optimization, as this guide defines it, is the practice of improving an agent so it completes tasks more reliably, at lower cost, and with less risk. Quality preservation is a primary success criterion, not an afterthought.
Every recalibration needs a blinded-judge evaluation: present pre- and post-recalibration outputs to an evaluator without labels. Statistically indistinguishable results confirm the recalibration is safe to ship. Without this gate, cost cuts can silently degrade the outputs that justified the agent's existence.
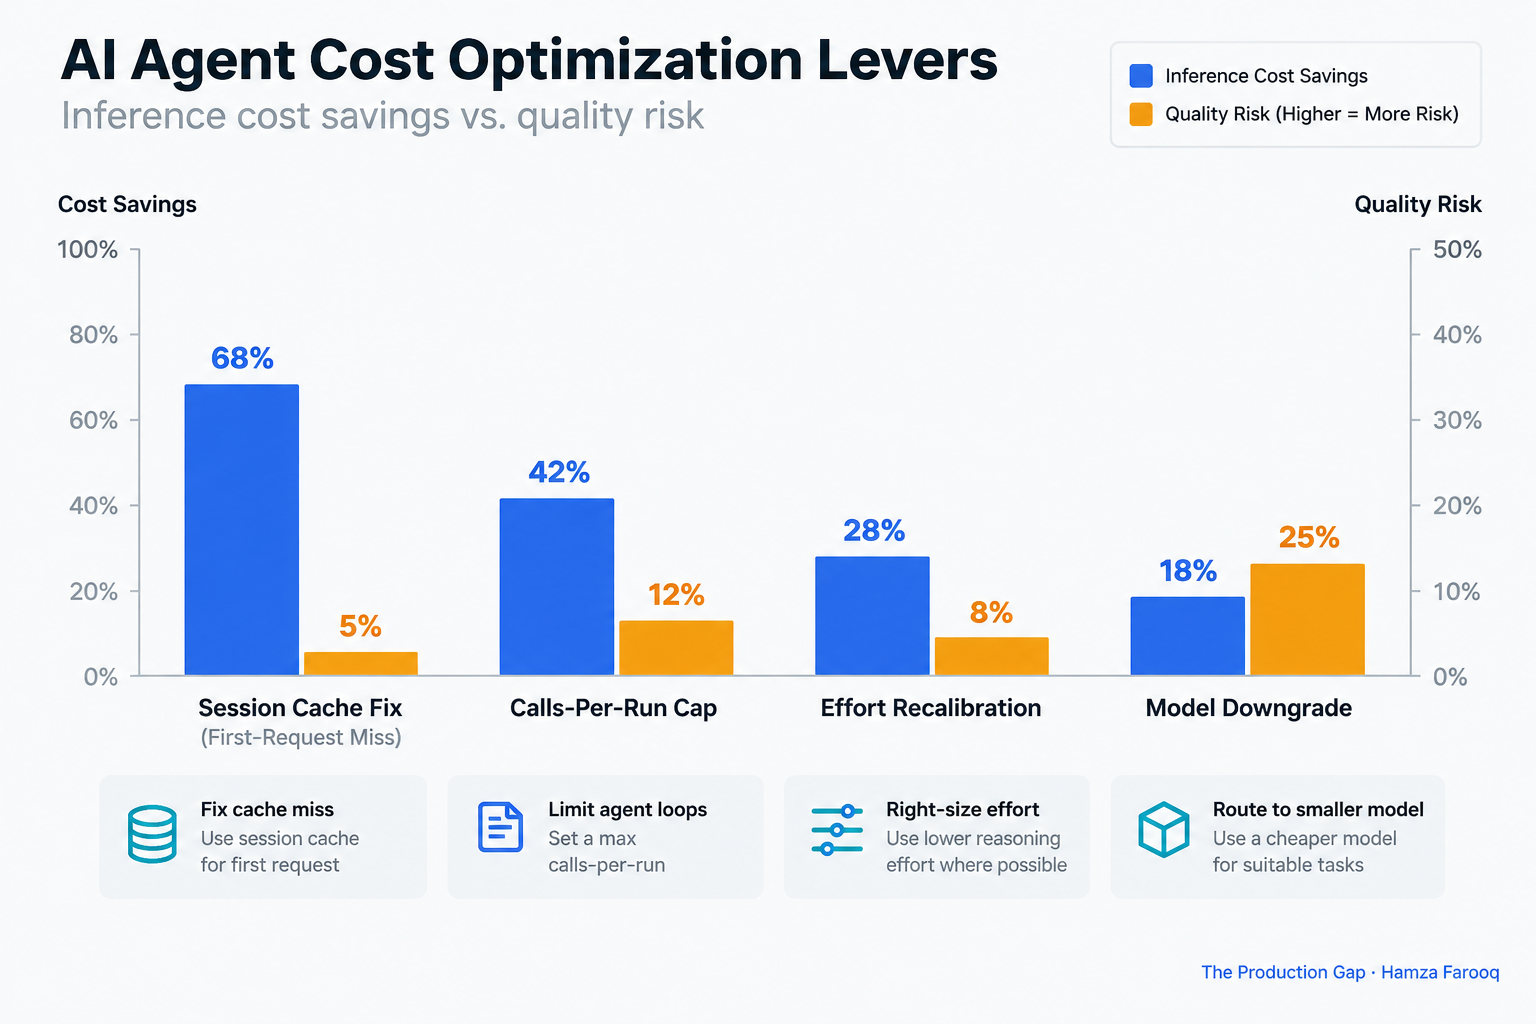
| Optimization lever | Requires model switch? | Quality risk | Typical cost impact | Evidence tier |
|---|---|---|---|---|
| Session-level cache fix | No | Low | High, eliminates cold-start full-price calls | Author synthesis, first audit to run |
| Calls-per-run cap | No | Low to Medium | Medium to High, removes outlier spend at p99 | Author synthesis, requires consumption ceiling |
| Effort-level recalibration | No | Medium (gate required) | Medium, reduces per-call compute budget | Author synthesis, needs blinded-judge eval |
| Model downgrade | Yes | High (gate required) | Variable, depends on routing logic | Last lever, not first |
How do you attribute agentic AI spend so the savings are actually visible to finance?
Spend attribution must be tracked at the workflow and session level, not the API-call level, because agentic workloads generate costs through autonomous loops that individual call logs cannot explain without session context.
A workable attribution schema tags every LLM call with four fields: workflow_id, session_id, call_sequence, and effort_level. This lets you roll up cost by workflow type, identify anomalous sessions, and filter effort-level spend separately. The AWS Agentic AI Well-Architected Lens names spend attribution explicitly as a cost design principle.
Once attribution is in place, set per-session and per-workflow token budgets, what the Lens calls "pay-per-task reasoning with consumption ceilings." Without a ceiling, a single runaway sub-agent loop can erase accumulated caching savings. Attribution is also the prerequisite for all three audit metrics: without it, none are queryable.
Frequently asked questions
How do you measure first-request cache hit rate separately from overall cache hit rate? Tag every LLM call with a session ID and sequential call index, then filter for call index equals 1. That filtered subset's hit rate is your true cold-start exposure, fully isolated from the aggregate figure that obscures it.
Can you reduce AI agent inference costs without switching to a cheaper model? Yes. Session-level cache fixes, calls-per-run caps, and effort-level recalibration can all reduce costs before model switching is necessary. Model switching is the last lever in the framework used in this guide because it carries the highest quality risk and cannot be safely applied without a blinded-judge evaluation gate.
What metrics confirm cost optimization is not degrading output quality? Run a blinded-judge evaluation presenting pre- and post-optimization outputs without labels. Statistically indistinguishable results confirm quality is preserved. Cost metrics and quality metrics must be tracked together: a cost reduction that degrades output quality fails the optimization on its own terms.
What is the right way to audit effort-level assignments to avoid severity inflation? Sample recent runs, record the assigned effort level and the actual complexity of the output produced, and calculate what percentage of high-effort assignments produced findings a lower-effort configuration could not have matched. That ratio is your effort inflation rate, and it is the metric that justifies recalibration.
Conclusion
The gap between a healthy-looking dashboard and a painful invoice is most often explained by cold-start misses hiding inside aggregate hit rates, ungoverned loops inflating calls per run, and effort-level assignments nobody has audited. None are model problems. All three are instrumentation and calibration problems that can be addressed before any model change is considered.
Your next step: Add call_sequence = 1 as a filter to your existing LLM cost dashboard. If your first-request miss rate is high, you have identified the most tractable cost driver in your pipeline and the one most dashboards are currently hiding from you.
Learn from me
Forward Deployed Engineering Bootcamp for Full-Stack Developers, my Maven cohort. Build and ship complete AI products end to end, from React and Node.js frontends to deployed models with caching and observability. Join the next cohort →
Hire us
Traversaal.ai. We're a team of forward deployed engineers solving the toughest AI problems for Fortune 100 companies: document intelligence, agentic data platforms, and real-time web intelligence, deployed in production. Work with our team to deploy your next agentic ecosystem. Talk to Traversaal.ai →
Join us
Want to solve these problems with us? We're always looking for forward deployed engineers who want to ship production AI. jobs@traversaal.ai